
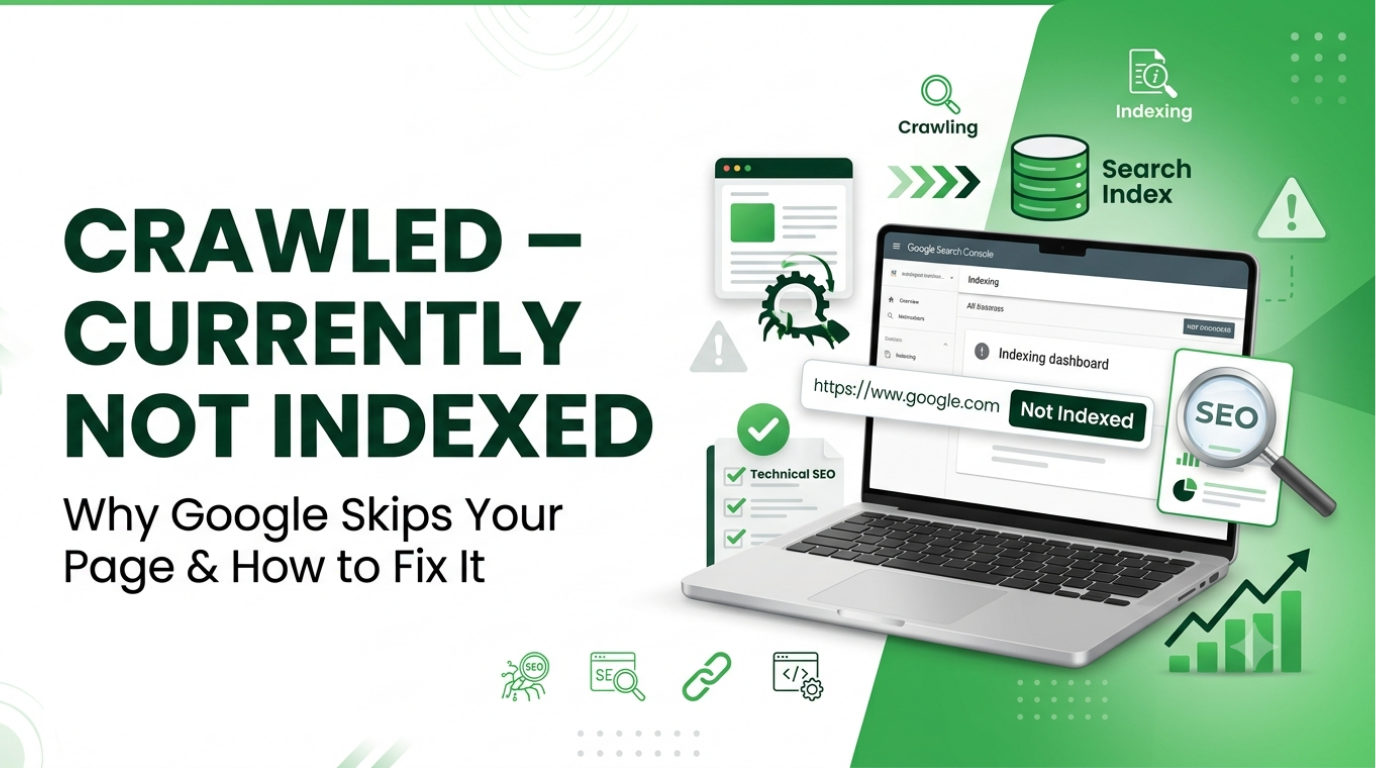
“Crawled – currently not indexed” means Googlebot has visited and read your page, but Google has decided, for now, not to add it to its search index. It is not a penalty. The usual causes are thin or duplicate content, weak internal linking, a misdirected canonical tag, a mismatch with search intent, or a website that has not yet earned enough trust. For most Indian businesses, from a Jaipur boutique store to a Bengaluru SaaS startup, the fix is to strengthen the page itself and its position inside the website. This guide from Kiefads explains how.
“Crawled – Currently Not Indexed” means Google has successfully crawled and evaluated your page but has chosen not to include it in the search index at this time. It is a quality and relevance decision, not a technical error or a manual action. The most common reasons are:
- Thin, generic or low-value content
- Duplicate or near-duplicate pages on the same website
- Weak or missing internal links
- A canonical tag pointing to another URL
- A page that does not match what people in India actually search for
Not every page needs fixing. If a page is useful, unique and properly linked, Google may index it naturally over time. Request Indexing should be the last step, not the first.
Why Would Google Crawl a Page and Then Refuse to Index It?
Google can crawl a page and still leave it out of the index because crawling and indexing are separate decisions, and the second one depends on quality and relevance. It is one of the more confusing statuses a site owner sees in Search Console, because Google did its job: it found the page, fetched it and rendered it, yet chose not to store it. In plain terms, Googlebot judged the page and decided it was not worth including, at least not yet. This is rarely permanent.
This happens a lot on Indian websites that scale quickly: city-wise service pages for a dozen metros, product variants on a D2C store, or hundreds of blog posts published to “cover keywords”. When Google sees many similar or shallow pages, it indexes a few and parks the rest.
A technical SEO audit checklist helps separate real technical faults from cases where Google simply needs stronger quality, relevance or site-level signals. The rest of this guide covers why the status appears, what an SEO professional checks first, and when the right move is to leave the page alone.
What “Crawled – Currently Not Indexed” Means in Search Console
When this label appears next to a URL in the Page indexing report, Googlebot reached the page, read its content and rendered it much like a browser would. What did not happen is the final step: inclusion in the index that powers search results. Because Google has already evaluated the page, the fix has to address whatever made Google pass on it.
Crawling and indexing are two separate decisions
The two terms are often used as if they mean the same thing, which causes confusion when diagnosing the problem. Understanding robots.txt vs noindex also matters, because they affect crawling and indexing in very different ways.
- Crawling is Googlebot visiting a URL and retrieving its content.
- Indexing is the later decision about whether that content earns a place in the searchable database Google draws from.
A page can clear the first hurdle without clearing the second. A product listing that loads perfectly but copies content already indexed elsewhere on your domain is a textbook example. Google will crawl it again and again, but sees little reason to store a second copy of something it already has.
Crawled vs Discovered: how to tell which one you have
Both labels sit in the same report, so they get mixed up. The quickest way to separate them is to ask whether Google has actually visited the URL.
| Status | What Google did | Where the problem usually sits | What to look at first |
|---|---|---|---|
| Crawled – currently not indexed | Visited the page, read it, then chose not to index it | The page: content, duplicates, canonical | Content depth, similar pages on your site, canonical tag |
| Discovered – currently not indexed | Found the URL but has not visited it yet | The site: crawl priority, internal links, server speed | Internal links, sitemap, number of low-value URLs |
To check, open Search Console, go to Pages and click the status. Then paste one affected URL into the URL Inspection tool. If “Last crawl” shows a date, you have a Crawled page. If it says “N/A”, it is Discovered.
Why Google Crawls a Page but Declines to Index It
In practice this status is rarely caused by one thing. Two or three factors usually stack up, and working out which one dominates is the real diagnostic work.
1. Thin or low-value content
This is the most frequent explanation. A page with sparse, generic text that does not properly answer the query it targets will not clear Google’s bar. Nothing needs to be technically broken. A 250-word “Best CA firm in Delhi” page with no fees, no process and no proof of work is a typical example.
2. Duplicate or near-duplicate content on the same site
Websites with many location pages, tag archives or near-identical product variants run into this constantly. Think of “SEO services in Noida”, “SEO services in Gurgaon” and “SEO services in Faridabad” with only the city name changed. Google tends to index one representative version and leave the close copies crawled but excluded. It is not a punishment, just a way to avoid redundant results.
3. A mismatch with real search intent
A page can be well written and still be passed over if it does not match what the searcher wants. If the target keyword implies a comparison or buying guide, but your page is a company announcement, Google may register the mismatch and decline to index it, whatever the writing quality.
4. Weak or missing internal linking
Pages with few or no internal links signal that your own site does not treat them as a priority. Orphan pages, or pages buried four or five clicks from the homepage, are heavily over-represented in this status.
5. A canonical tag pointing elsewhere
Sometimes the page’s canonical tag names a different URL as the preferred version. Google respects that instruction and will not index the current page, even when this outcome was never intended. This is common after a CMS migration, a theme change or a plugin update.
6. Limited site authority and crawl budget
On newer or lower-authority domains, Google is more selective about what it commits to indexing. Content that would be indexed instantly on an established domain can be skipped simply because the site has not yet built enough trust. A poorly organised website structure also makes important pages harder for Google to discover, understand and prioritise.
How to Fix “Crawled – Currently Not Indexed”
Work through the steps below in order. The early steps take minutes and rule out the easy causes. The later ones need real work on the page, so do not jump straight to Request Indexing.
Pre-fix audit checklist
Before changing anything, answer these five questions for the affected page:
- Does the page offer something meaningfully different from similar pages already on your site?
- Is it linked from at least a handful of relevant pages that are already indexed?
- Does the canonical tag point to itself, or elsewhere only by deliberate choice?
- Does the content match what someone searching the target keyword in India actually wants?
- Is the page included in your current XML sitemap?
The fix order
- Confirm the status. Test the live URL in URL Inspection. If it shows as indexed, stop here. The report was out of date.
- Fix the technical mismatches. A wrong canonical, a missing sitemap entry or an accidental noindex tag are quick wins.
- Check for duplicates. Search
site:yourdomain.com "a distinctive sentence from the page". If another page covers the same ground, merge the two or differentiate this one. - Add internal links. Link to the page from two or three relevant, already-indexed pages using descriptive anchor text.
- Rework the content. Compare your page with what ranks for the query. Add what is missing: first-hand detail, a real example, a screenshot, local context such as prices in ₹, GST details or city-specific information, and a clear answer near the top.
- Resubmit the sitemap, then request indexing once. Do this after steps 1 to 5, not before.
- Wait two to four weeks, then re-check. If nothing has changed, go back to step 5. The cause is almost always the content, not the settings.
What not to do
- Do not click Request Indexing every day. It does not speed up Google’s decision.
- Do not delete and republish the page or change its URL. You lose its history and gain nothing.
- Do not add noindex just to clear the report.
- Do not buy links or use “indexing services” to force indexing. These are a common trap for Indian site owners.
- Do not mass-delete pages before checking which ones bring traffic.
Edge Cases: Pages That Show This Status but Do Not Need Fixing
Some URLs land in this report for harmless reasons. Check these before spending time on fixes.
| Edge case | What happens | What to do |
|---|---|---|
| Pagination pages | URLs like /blog/page/2/ often appear here. The posts they list are indexed on their own. | Leave them. |
| RSS and feed URLs | /feed/ and /comments/feed/ get crawled but are not meant for search. | Ignore them. |
| Parameter and tracking URLs | URLs with ?utm_source= or ?replytocom= duplicate a page that is already indexed. Indian sites running WhatsApp and Instagram campaigns see many of these. | Make sure each has a canonical to the clean URL. |
| Image files such as WebP | A standalone .webp or .jpg URL can appear when something links to it directly. It is a file, not a page. | No action. Images can still appear in Google Images through the pages that use them. |
| False positives | The report updates slowly. A URL can show as not indexed while URL Inspection says it is indexed. | Always trust the live inspection over the report. |
| Pages you should not index | Thank-you pages, internal search results, login pages, and tag archives with one post. | Their absence is usually fine. |
When the Correct Response Is to Leave the Page Alone
Not every case needs active intervention. New pages, lower-priority pages and pages on sites that publish often can sit in this status for a while and resolve on their own as Google reassesses the site. If a page is genuinely useful, reasonably well linked and not duplicating existing content, patience is usually the better course. Repeated use of Request Indexing does not speed up the underlying evaluation and can pull crawl attention away from pages that need it.
Sites that see this status across many pages usually have a structural or content-quality problem that the Page indexing report alone cannot show.
Get a Clear Diagnosis from Kiefads
Kiefads provides a comprehensive website and technical SEO audit for Indian businesses that explains exactly why Google is declining to index specific pages. The audit examines crawl budget allocation, internal linking architecture, canonicalisation and content quality, then delivers a prioritised action plan instead of a list of guesses. Whether you run an e-commerce store, a local service business or a B2B website, request an audit from Kiefads to get a clear diagnosis for your site.
Frequently Asked Questions
What is the difference between “Crawled – currently not indexed” and “Discovered – currently not indexed”?
With “Crawled”, Google visited the page, read it and chose not to index it, so the problem usually lies in the page itself. With “Discovered”, Google knows the URL exists but has not visited it yet. That points to crawl priority or site-level signals rather than content.
Is this status harmful to my site’s SEO more broadly?
A few affected URLs are normal and usually harmless, especially pagination, feeds and parameter URLs. A large or growing number of important pages in this status can point to site-wide quality, duplication or internal linking issues, which do limit organic traffic and leads.
How long does it take before Google reconsiders indexing?
There is no fixed timeline. After you improve the page and add internal links, allow roughly two to four weeks before re-checking. Pages on newer or low-authority websites can take longer.
Does clicking Request Indexing guarantee a fix?
No. It asks Google to look at the URL again, but it does not change Google’s judgement of the page. If the content, duplication or linking problem remains, the status will usually come back.
Can a canonical tag, noindex tag or robots.txt cause this status?
A canonical tag pointing to another URL can, because Google follows it and skips the current page. A noindex tag normally shows up as “Excluded by ‘noindex’ tag” instead. A robots.txt block stops crawling altogether, so the page would not appear as crawled.
Is this status always a problem, or can I ignore some URLs?
It is not always a problem. Feeds, pagination, tracking-parameter URLs, thank-you pages and standalone image files can safely be ignored. Focus on pages that should bring in traffic or leads, such as service pages, product pages and blog posts.
Do internal links help a page get indexed?
Yes. Internal links tell Google which pages matter and help it understand how they relate to the rest of your site. Linking a page from two or three relevant, already-indexed pages with descriptive anchor text is one of the most effective and cheapest fixes.